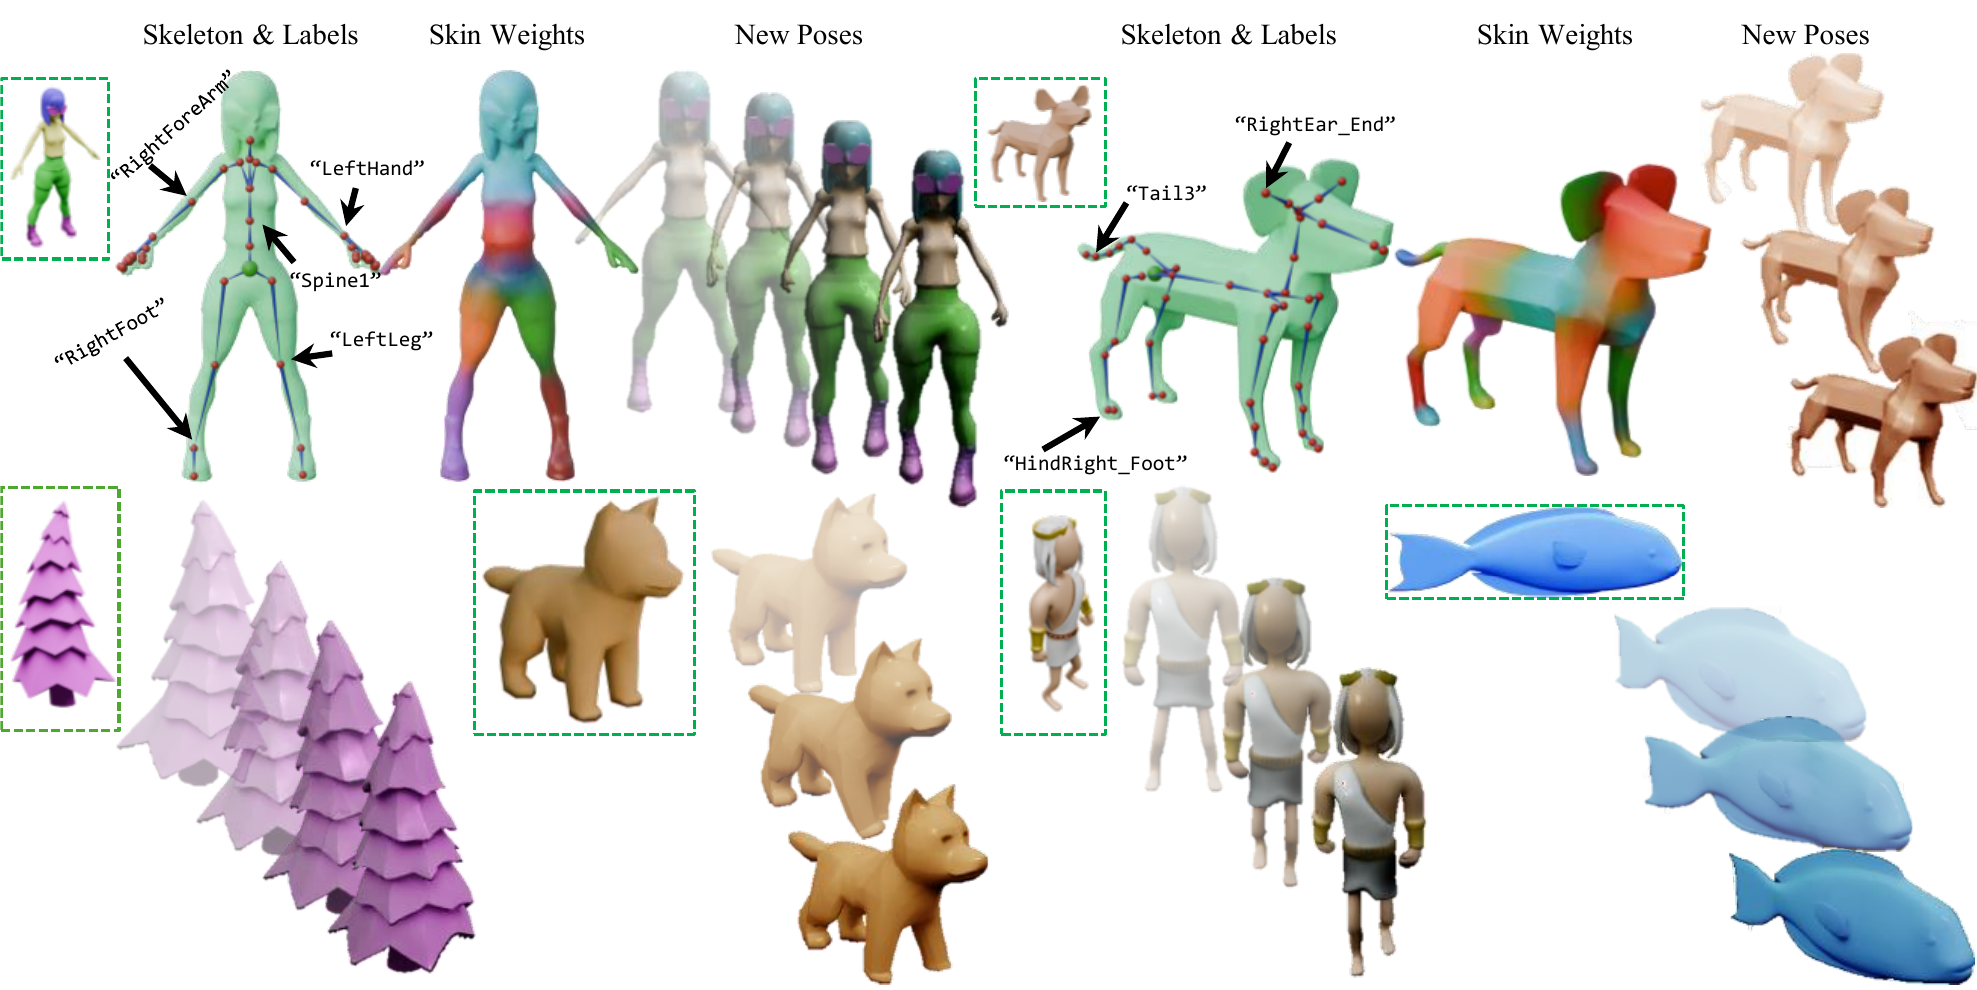
More animated examples, source code and checkpoints coming soon!
Recent 3D generative models can synthesize high-quality assets, but their outputs are typically static: they lack the skeletal rigs, joint hierarchies, and skinning weights required for animation. This limits their use in games, film, simulation, virtual agents, and embodied AI, where assets must not only look plausible but also move plausibly. We introduce Rigel3D, a generative method for animation-ready 3D assets represented as rigged meshes. Unlike post-hoc auto-rigging methods that attach rigs to completed shapes, our method jointly models geometry and rig structure through coupled surface and skeleton structured latent representations. A rig-aware autoencoder decodes these representations into mesh geometry, skeleton topology, joint coordinates, and skinning weights, while a two-stage latent generative model synthesizes both surface and skeleton representations for image-conditioned generation. To support downstream animation workflows, we further introduce an open-vocabulary joint labeling module that embeds generated joints into a shared vision-language space, enabling correspondence to arbitrary retargeting templates. Experiments on large-scale rigged asset datasets demonstrate that our method generates diverse, high-quality animation-ready assets and outperforms existing rigging baselines across multiple metrics.
Overview of the rig-aware autoencoder. A surface encoder produces surface SLats from multiview visual features attached to occupied surface voxels, while a skeleton encoder produces skeleton SLats from rig-aware features attached to voxels intersecting the bones. The two latent representations are jointly decoded into mesh geometry, skeleton structure, and skinning weights.
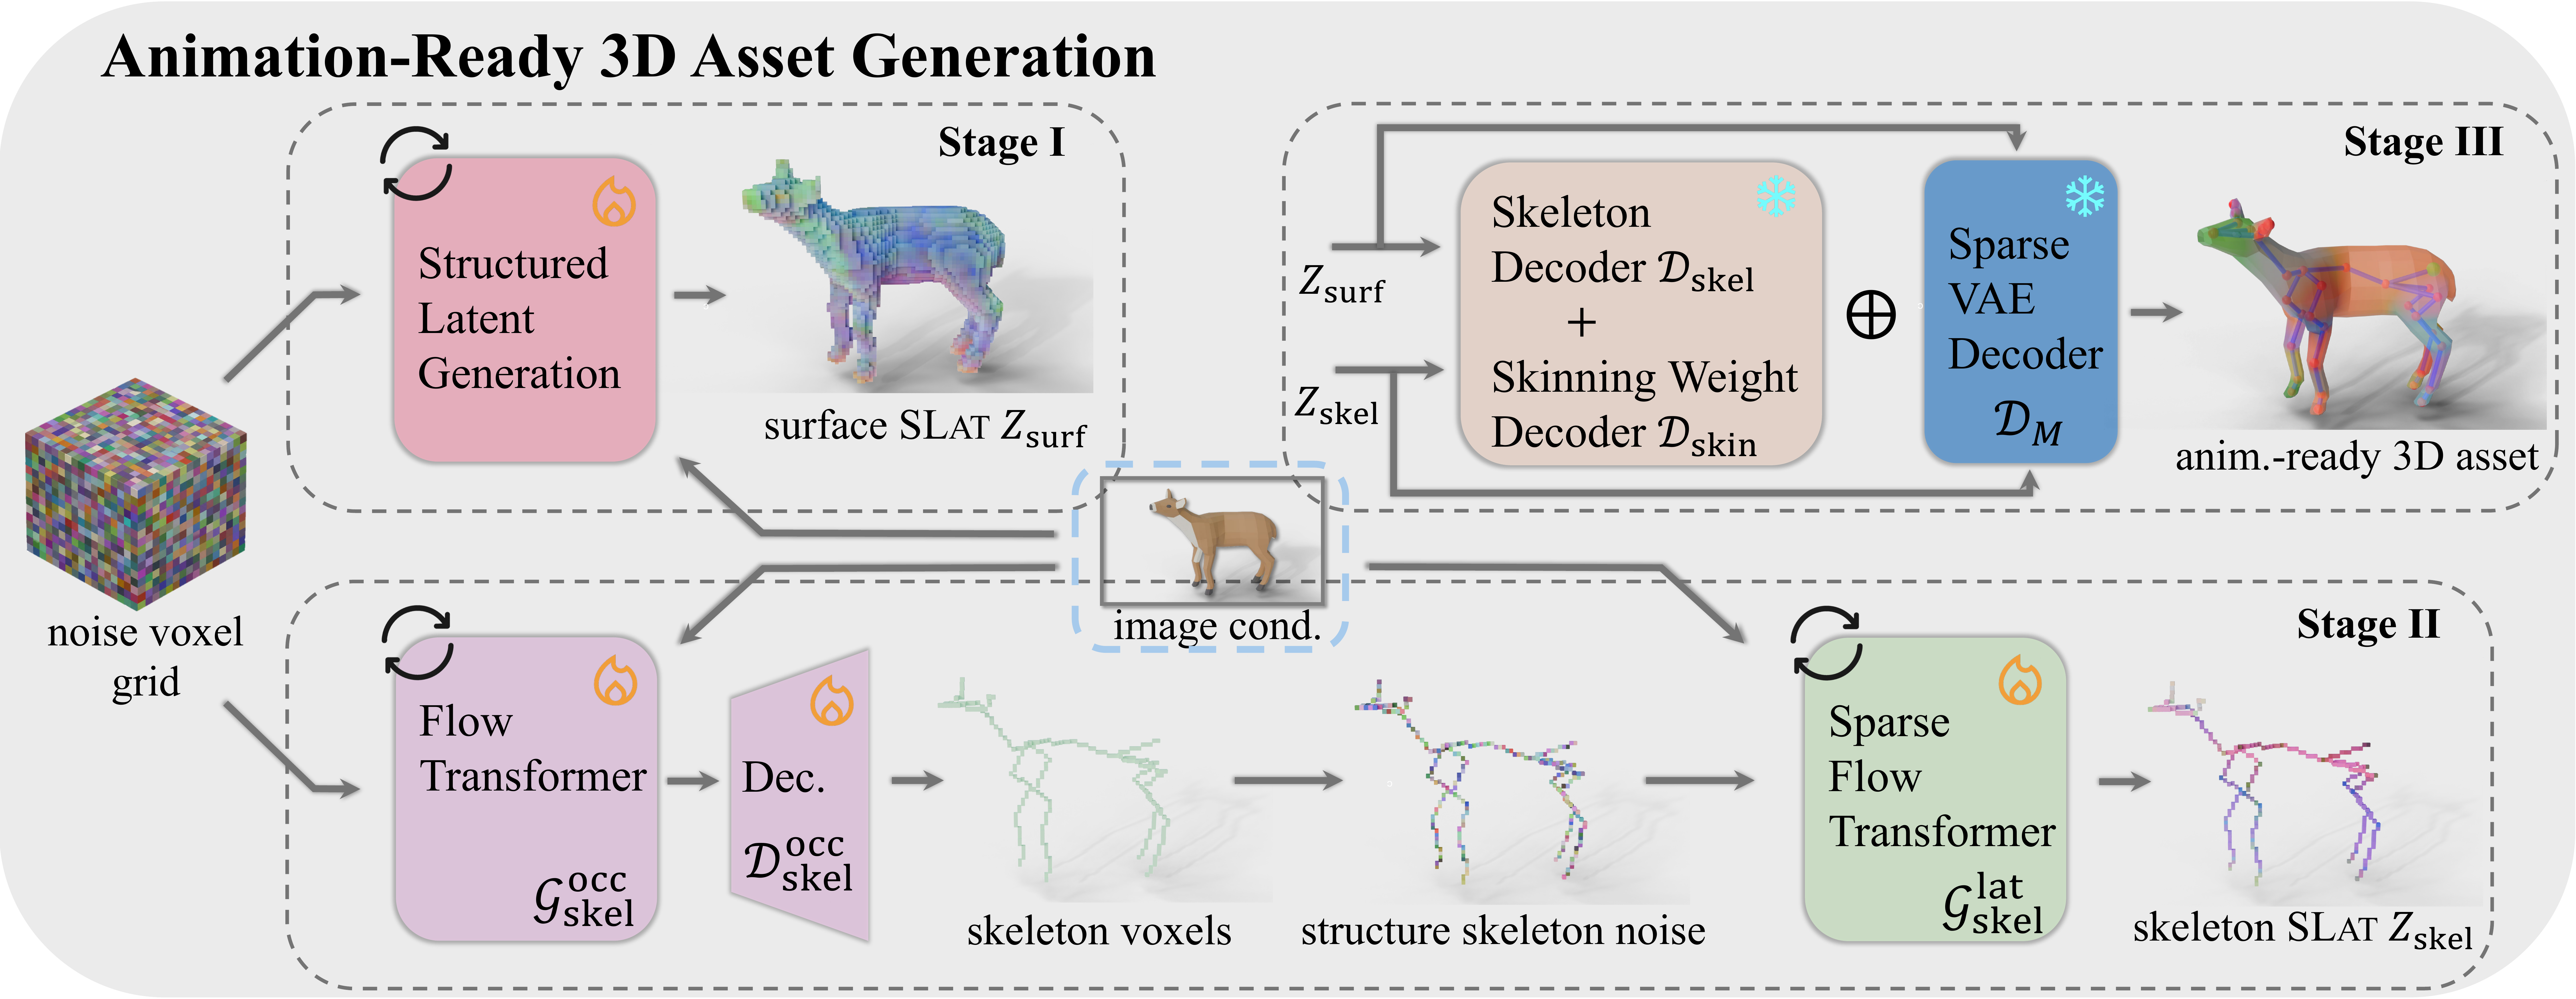
Overview of the generator. Conditioned on an input image, our generation pipeline yields both surface and skeleton SLats, which then are decoded into mesh geometry, skeleton structure, and skinning weights.
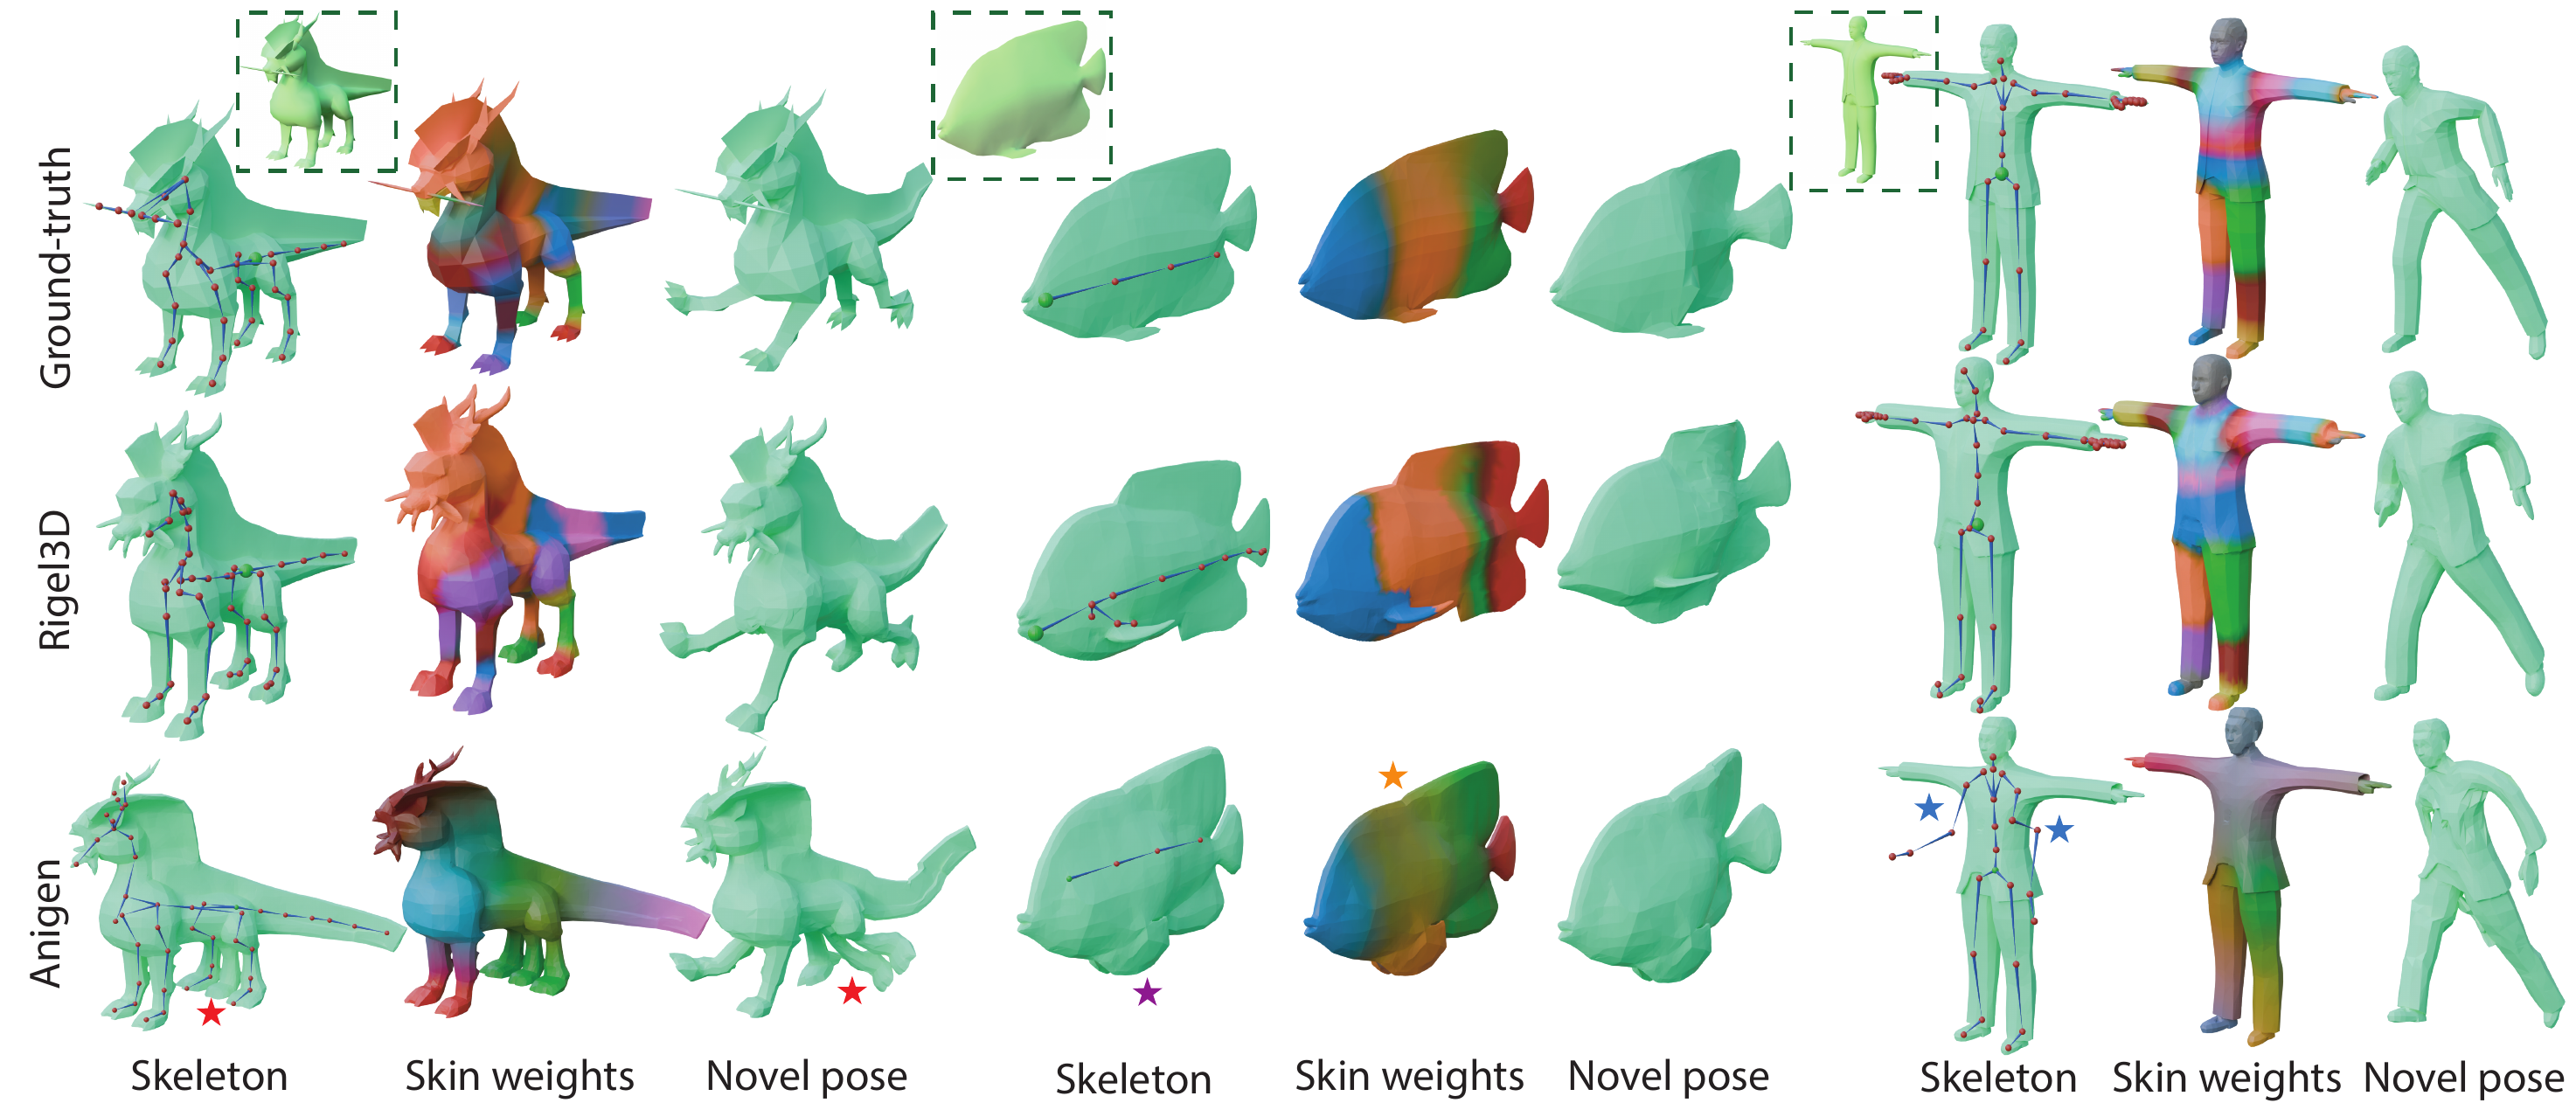
Anymate dataset experiments. We compare our method to two-stage baselines (TRELLIS + post-hoc auto-rigging). Rigel3D produces rigs that better match the reference ones in joint placement, connectivity, and skinning while yielding more coherent novel poses. Shapes are shown without texture to emphasize skeleton and pose geometry rather than appearance. Skinning colors indicate bone influence, with smooth transitions corresponding to blended weights. Green insets show input images.
ArticulationXL-1k test split experiments. Here we compare generated shapes, skeletons, skinning, and novel-pose deformations. Green insets show input images. Under our evaluation protocol, Rigel3D better preserves the articulation structure and produces more coherent skinning weights across diverse assets. Stars highlight issues such as extra generated limbs, incomplete geometry, incorrect skinning weight distribution and spurious joint placement.
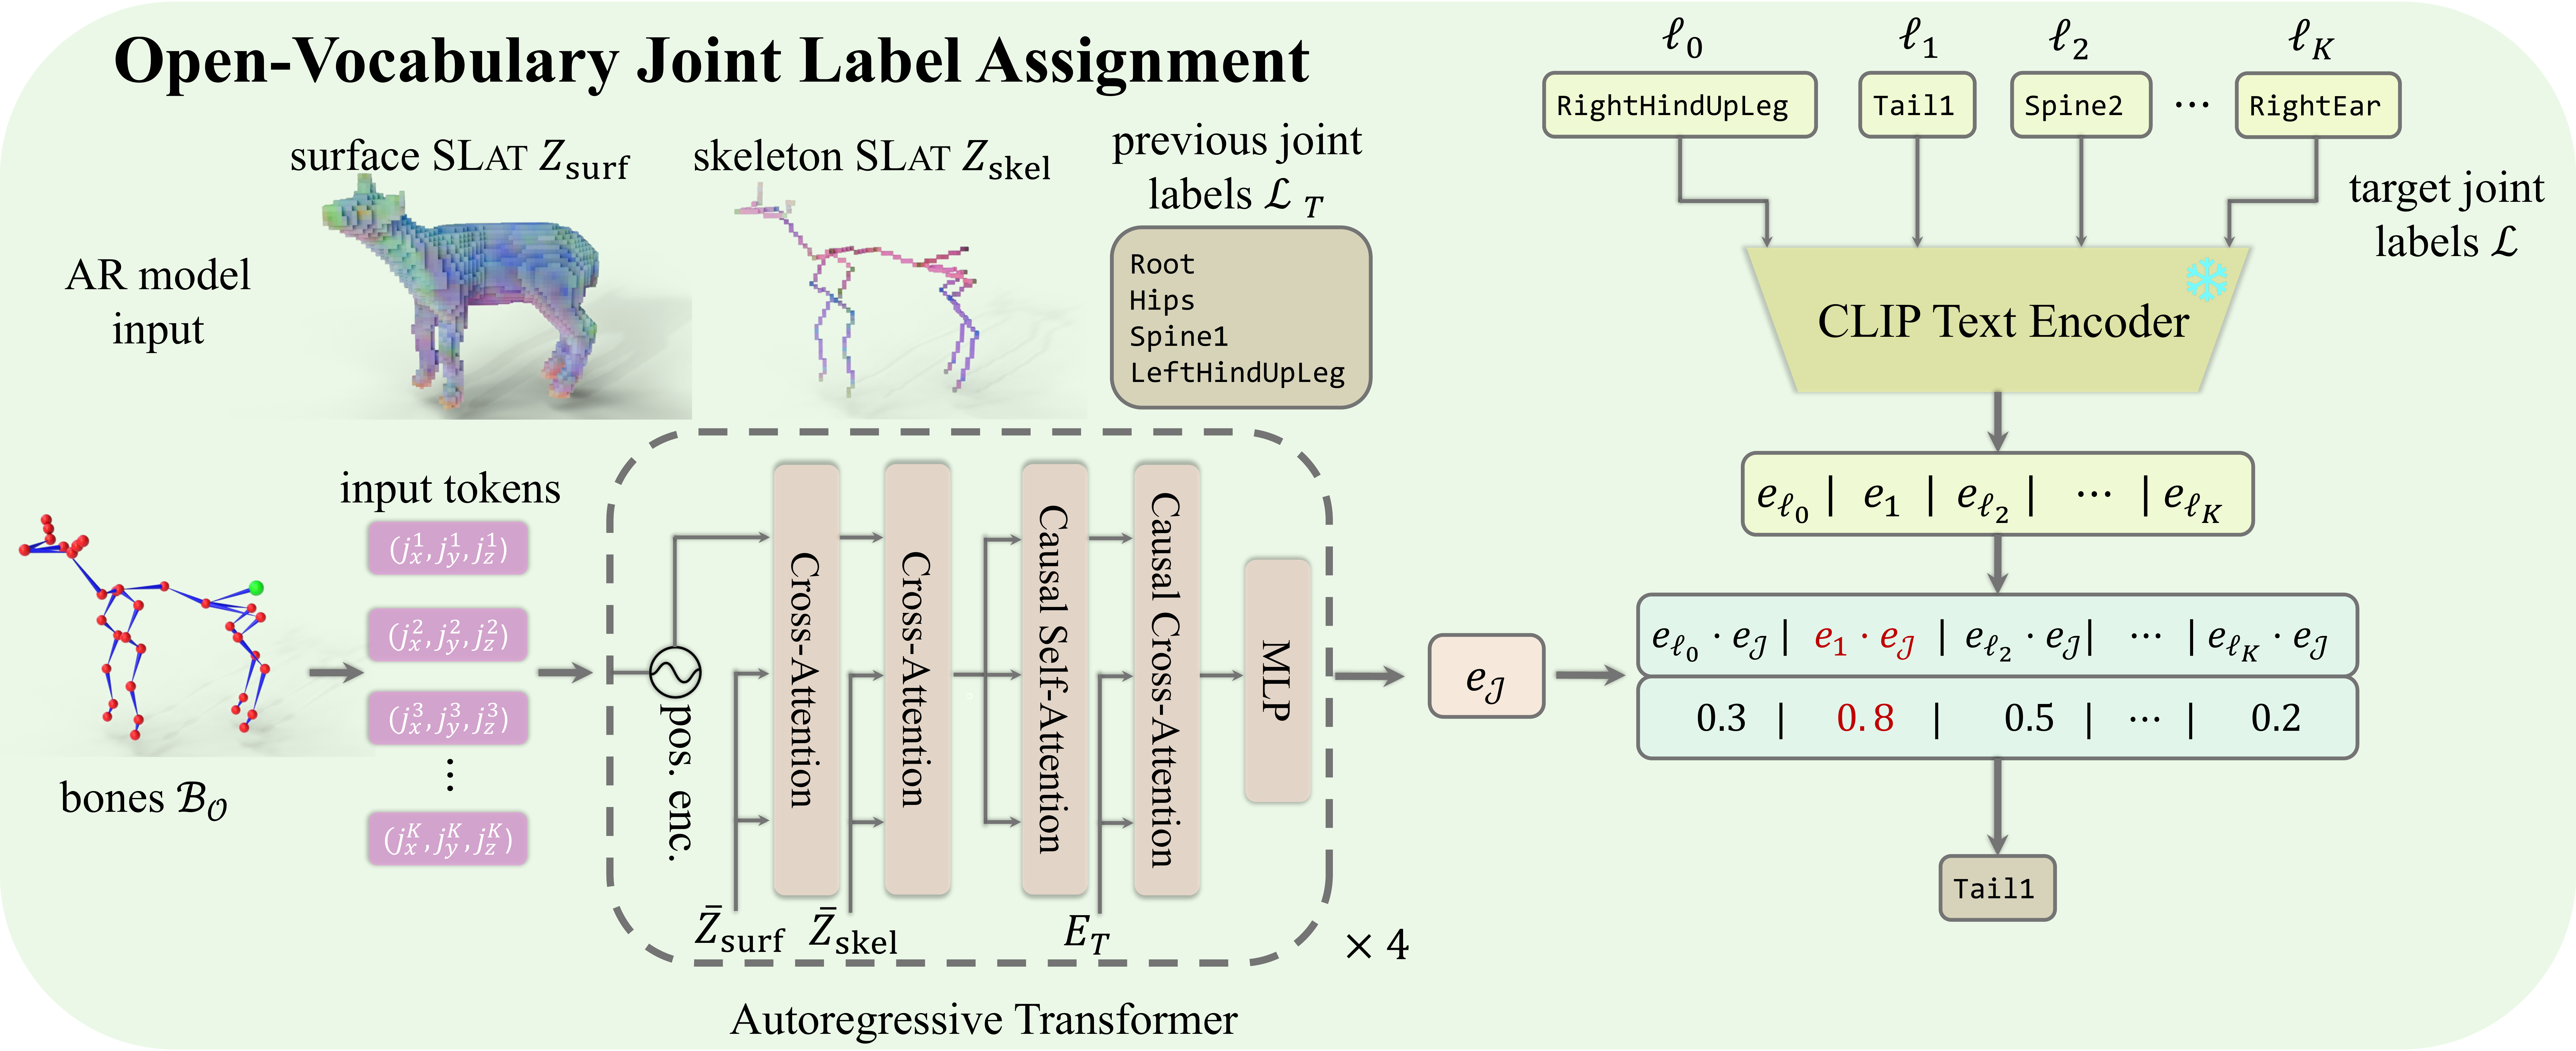
Skeleton labeling. Our labeling model coembeds skeleton geometry and text captions, allowing for label querying and further compatibility with downstream animation pipelines. At inference time, each generated joint is labeled by nearest-neighbor retrieval over any candidate vocabulary, including joint names of a retargeting template. Thus, the learned joint representation is decoupled from the choice of label set, allowing the same rig to be matched to different animation templates without retraining.
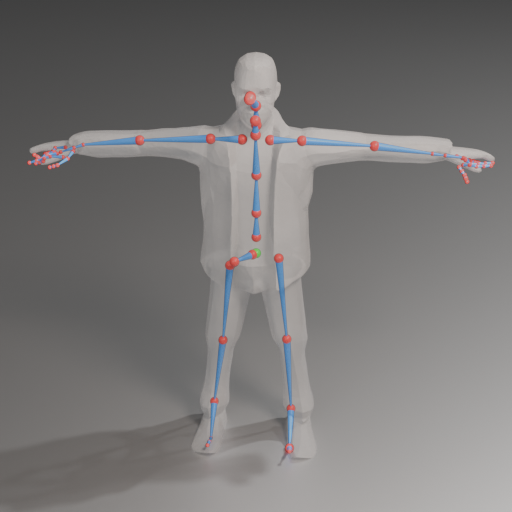
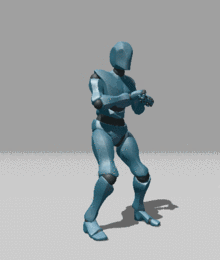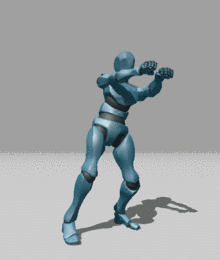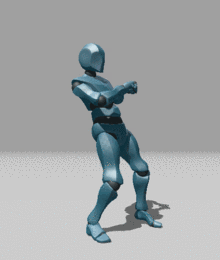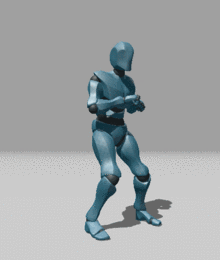
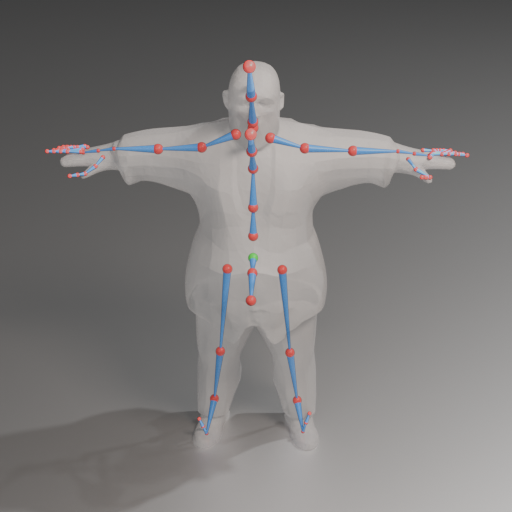
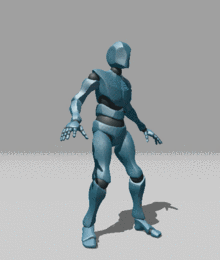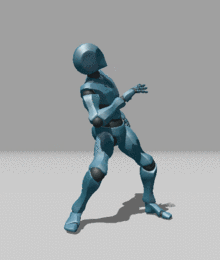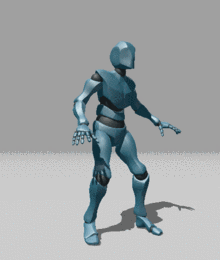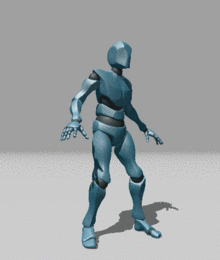
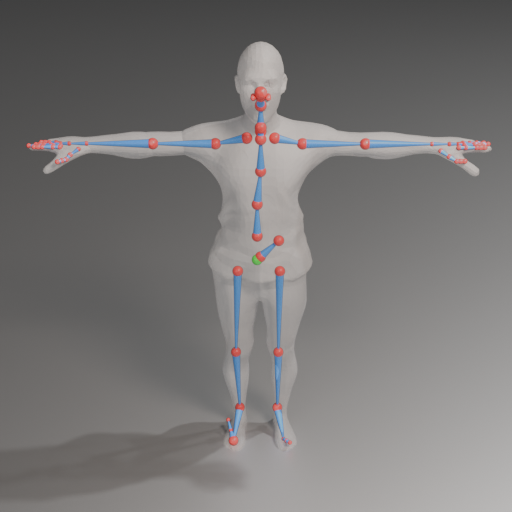
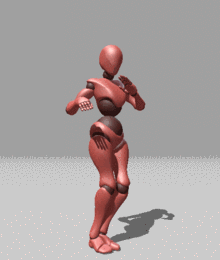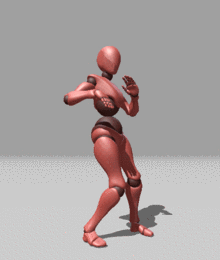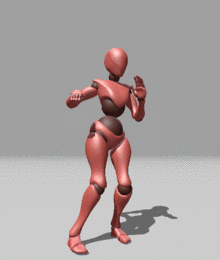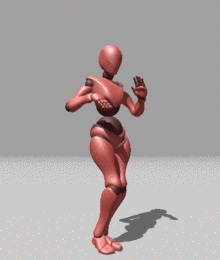
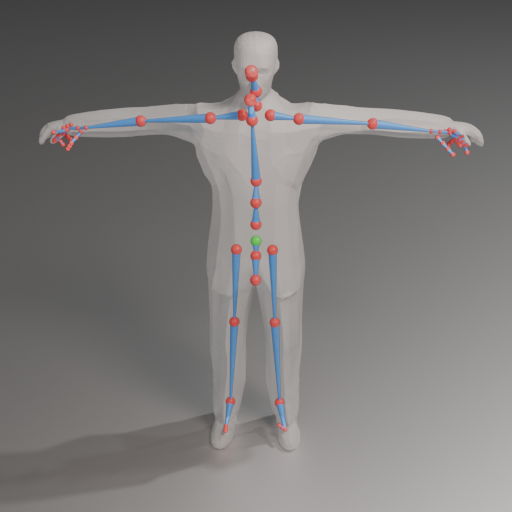
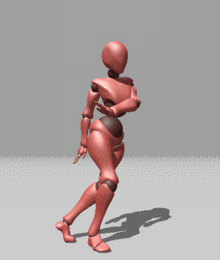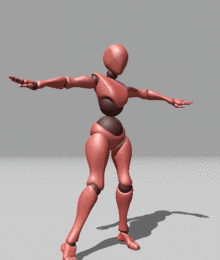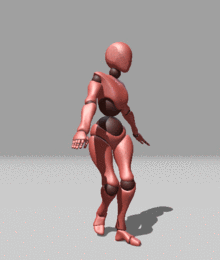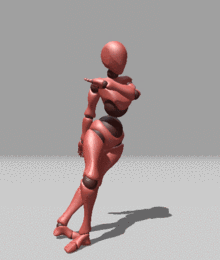
Our generated animation-ready asserts are labeled with our open-vocabulary module given a list of joint labels from a corresponding template. The source motion is then retargeted onto our generated asset. All animations are sourced from Adobe Mixamo. **Blender stores multi-child connections as hierarchy links rather than exact head-to-tail bones, as seen in the hip–spine–leg junctions and the upper spine, neck, and shoulder area. These links are not drawn in the proxy geometry rig, so some visual segments may appear missing, although the actual rig remains connected and animates correctly.
@article{chatzis2026rigel3d,
      title={Rigel3D: Rig-aware Latents for Animation-Ready 3D Asset Generation},
      author={Nikitas Chatzis and Marios Loizou and Evangelos Kalogerakis},
      journal={Advances in Neural Information Processing Systems},
      year={2026},
}